Data Engineering, Pipelines & Analytical Warehousing
Stop making decisions on stale data and brittle spreadsheets. We design, deploy, and maintain enterprise-grade data pipelines, modern cloud warehouses (Snowflake, BigQuery), and executive BI dashboards.
Custom scope & retainer arrangements tailored to your infrastructure requirements.
Capabilities
End-to-End Data Engineering Services
From raw transactional ingestion to boardroom decision dashboards, we engineer every layer of your modern data stack.
Real-Time Streaming & Event Ingestion
Capture and process events as they happen with zero data loss and sub-second delivery.
- Apache Kafka & AWS Kinesis cluster deployment
- Event-driven pub/sub architecture and schema registries
- Stream deduplication & validation workers in Python / Spark
- Microservice change data capture (Debezium / PostgreSQL CDC)
Cloud Data Warehousing & Lakehouse
Consolidate fragmented business data into a single, high-speed analytical source of truth.
- Snowflake & Google BigQuery architecture design
- Raw, Bronze, Silver, and Gold medallion layer modeling
- Separation of compute and storage to optimize operational costs
- ClickHouse integration for low-latency customer-facing queries
Transformation & Data Modeling (dbt)
Turn raw messy data into reliable, tested, and documented analytics models.
- dbt core and dbt cloud pipelines with version control
- Automated schema validations, freshness, and relationship tests
- Dimensional modeling (Star & Snowflake schemas) for BI tools
- Automated data lineage documentation and dictionary generation
Workflow Orchestration & Automation
Reliable scheduling and automated recovery for batch and incremental syncs.
- Apache Airflow and Prefect programmatic DAG development
- Automated retry mechanisms and dead-letter queue routing
- Data pipeline health monitoring and Slack/Email incident alerting
- Automated infrastructure teardown to prevent idle cloud billing
Executive BI & Analytics Dashboards
Transform raw warehouse queries into intuitive decision-making dashboards.
- Custom interactive Power BI, Tableau & Apache Superset suites
- Automated executive KPI tracking (CAC, LTV, Retention, ROAS)
- Role-based dashboard permissions and row-level security
- Embedded analytics dashboards inside your customer web apps
Data Governance & Compliance
Protect sensitive data while ensuring engineering teams have fast access.
- PII data masking and role-based access control (RBAC)
- Audit logging and GDPR / DPDP Act 2023 compliance architecture
- Data retention and automated archival policies
- Disaster recovery and automated warehouse backup snapshots
Our Engineering Process
How we design and deploy your data infrastructure
Every data project follows our disciplined four-stage engineering methodology.
Data Audit & Schema Discovery
We catalog your current data sources, schema changes, query bottlenecks, and reporting requirements. We deliver a clear architecture blueprint before any infrastructure is provisioned.
Pipeline Ingestion & Lakehouse Setup
We establish resilient ELT connectors or real-time Kafka topics, configure the cloud warehouse (Snowflake/BigQuery), and implement automated schema migrations and security guardrails.
dbt Modeling & Quality Assertions
We write modular, version-controlled SQL transformations in dbt. We enforce automated tests so bad data from upstream APIs is trapped and alerted before polluting executive reports.
Analytics Delivery & Handover
We wire up your Power BI, Tableau, or web application dashboards, verify analytical calculations with your finance/operations leaders, and hand over complete documentation and code.
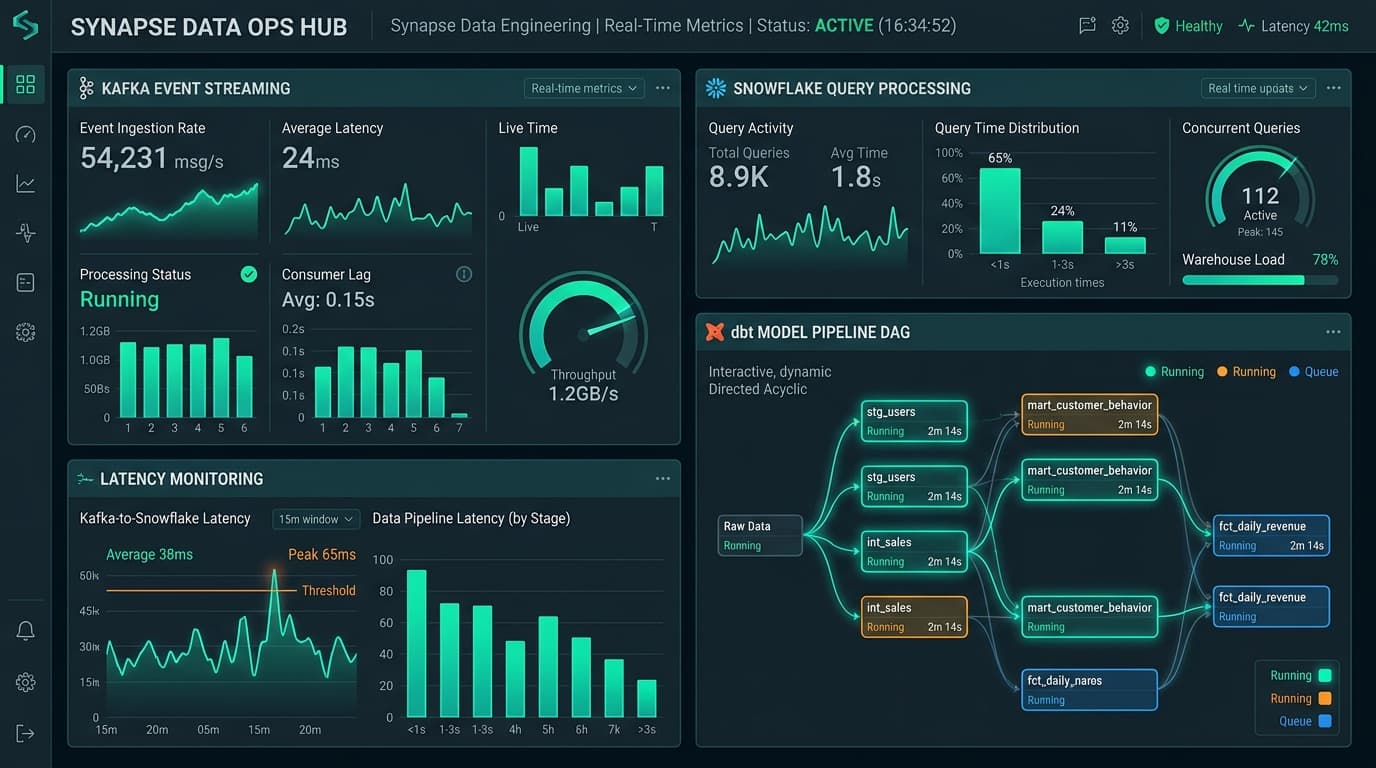
ApexMetrics: From 6-hour batch delays to 42ms query speed
Discover how Pihow architected an Apache Kafka streaming pipeline and Snowflake warehouse processing 50M+ daily transactions with 99.99% reliability.
42 ms
Average Latency
50M+
Daily Events
38%
Cloud Cost Saved
99.99%
Pipeline SLA
Ready to upgrade your data infrastructure?
Tell us about your current data sources, volumes, and analytical goals. We'll prepare an architectural recommendation and scoping roadmap.